Turn Web Data into Actionable Content With
Autonomous AI Crawling & Editorial Pipelines
Stop manually aggregating news, competitor prices, or industry feeds. We build resilient web crawlers that decode complex redirects, run multi-stage LLM analysis, and syndicate quality content across the web, decentralized networks, and messaging channels.
Hours spent monitoring fragmented web sources
Businesses need timely intelligence—whether tracking market rates, curating an industry newsletter, or monitoring competitors. Doing this manually means opening 20 browser tabs, wrestling with paywalls, coping with redirect tracking, and writing summaries from scratch.
- Manual web surfing consumes hours of skilled employee attention.
- Google News wrappers and anti-bot systems block generic scrapers.
- Inconsistent output format and zero automated syndication to followers.
Automated scraping, AI editorial curation, instant reach
We engineer custom pipelines that bypass redirect layers (e.g. decoding complex base64 Google redirect tokens), extract clean article bodies, run calibrated multi-stage LLM prompts (from executive summaries to biting satire), and syndicate directly to static websites, Bluesky (AT Protocol), and chat bots.
- Resilient scraping with DNS-over-HTTPS and fallback parsers.
- Fact-anchored LLM synthesis tailored strictly to your editorial voice.
- Autonomous cross-platform syndication via AT Protocol and RSS.
Engineered for Data Reliability
How we overcome common web scraping and content generation roadblocks.
Dynamic Redirect & URL Decoding
Google News and aggregator feeds wrap destination URLs in client-side base64 redirect tokens. Our custom decoders resolve authentic canonical URLs without getting blocked.
Multi-Stage LLM Editorial
Raw text is cleaned of cookie popups, analyzed for core factual claims, and synthesized into concise commentary and social media snippets adhering to strict length and tone constraints.
Decentralized AT Protocol Syndication
Broadcast directly to Bluesky and modern social protocols using authenticated cryptographic session signing, expanding audience reach beyond traditional walled gardens.
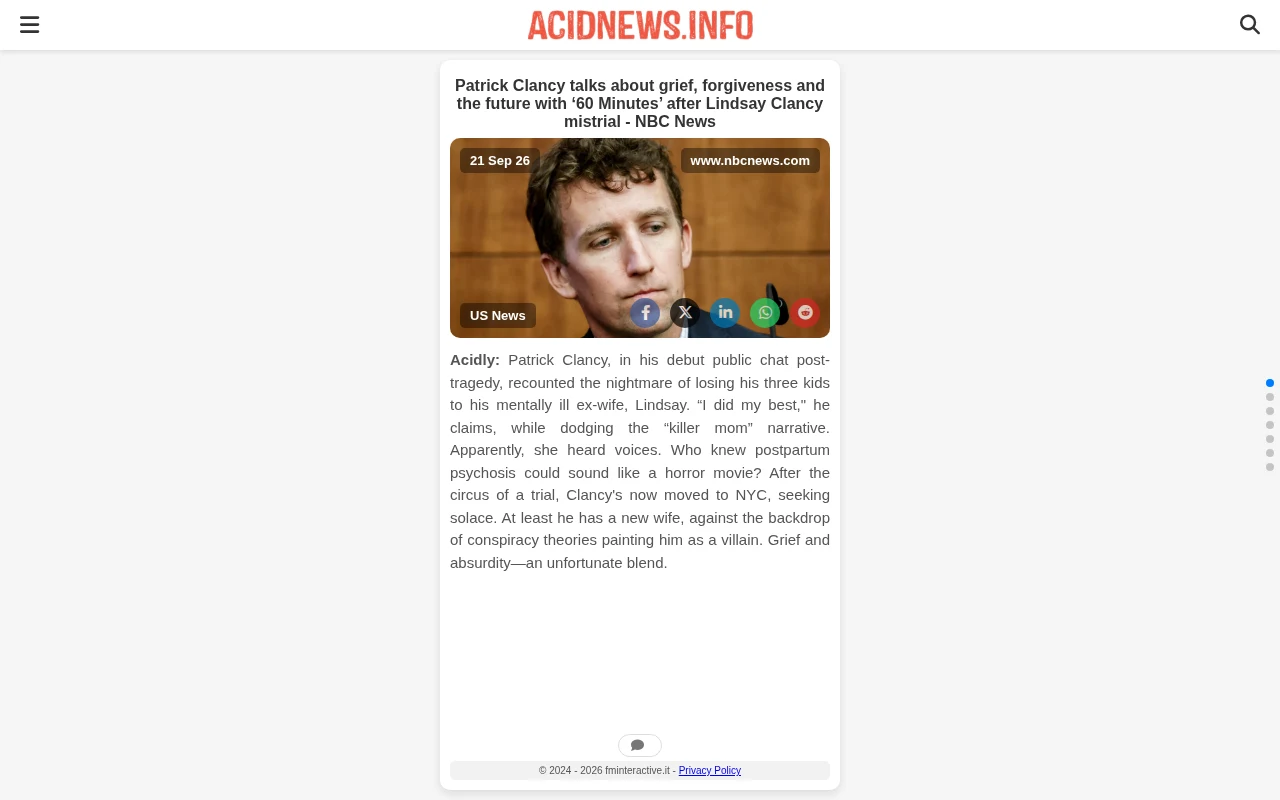
AcidNews & NotizieAcide: Fully Autonomous AI Newsrooms
Two independent digital news properties running 100% autonomously for over 2 years.
Daily Satirical Editorial Automation
Every morning at 07:00 UTC, the pipeline ingests Google News RSS topics, unshortens URLs, extracts clean article bodies, generates satirical commentary with GPT-4o-mini, and publishes a static carousel site with zero database delay.
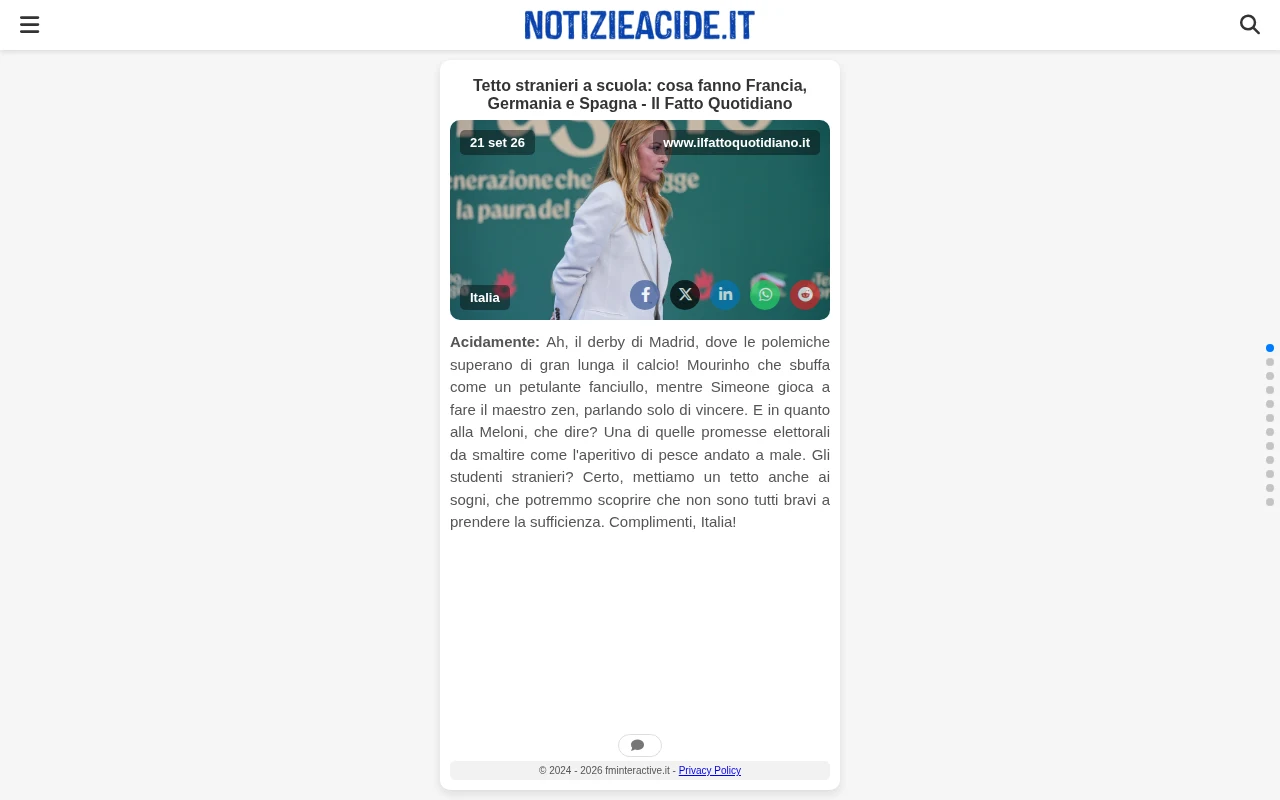
Italian AI Media + Bluesky AT Protocol
Adapted for the nuances of Italian political and cultural satire. In addition to web publishing, every article is syndicated automatically to Bluesky via AT Protocol with customized social cards and hashtag strategies.
Data Scraping & AI FAQs
Is web scraping legal and safe for my business?
Yes, when conducted ethically on public data without accessing password-protected areas or violating rate limits. We respect robots.txt guidelines and implement caching so our crawlers never stress target servers.
How do you prevent the AI from making up facts?
Our multi-stage pipeline anchors the LLM strictly to the extracted source text. The model is instructed to synthesize and analyze only verified facts present in the raw article body, eliminating external hallucinations.
Can the output be piped into an internal Slack or email feed?
Yes. Extracted and summarized data can be sent wherever you need it: private Telegram or Slack channels, automated daily executive email digests, SQLite/PostgreSQL databases, or static web dashboards.
Need Automated Web Intelligence?
Tell us what data, competitor feeds, or news topics you need extracted and summarized. We'll build an autonomous engine for you.